Infinite Loops: How AI Improvement Builds on Itself
Infinite Loops: How AI Improvement Builds on Itself
When an Infinite Loop Stops Being a Mistake
In traditional programming, an infinite loop usually means something has gone wrong. The program keeps repeating without reaching a stopping point. It consumes resources but never finishes the job.
With AI, we see different possibilities.
Not an agent running forever. Not a draft revised endlessly. But a cycle of improvement that makes your work, and the way you work, better with each cycle.
Start with a recurring task. You use AI to produce a result, evaluate it, and correct what falls short. Then you realize AI can also help improve the prompts behind that result. Once the process is reliable, you use AI to help turn it into an agent. And when that agent saves you time, you reinvest some of that time in deciding what to build next.
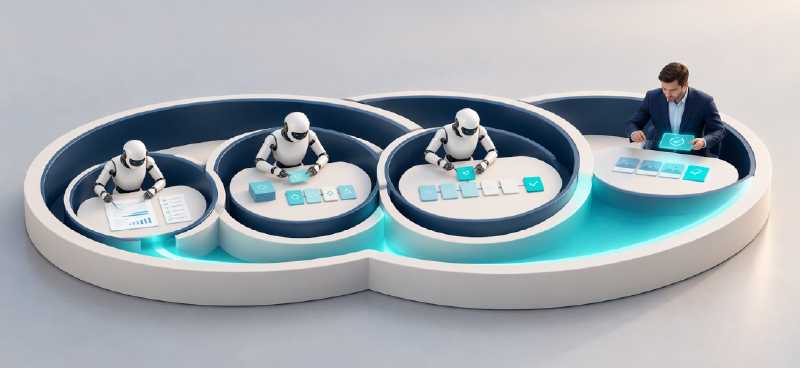
That is why we call them infinite loops, in the plural. There is not one feedback cycle. There are loops within loops:
- Improve the result: Use AI to evaluate and refine what it produces.
- Improve the prompts: Use AI to strengthen the instructions and quality criteria behind the work.
- Improve the automation: Use AI to build, test, and refine the workflow or agent that executes it.
- Choose the next opportunity: Use AI to help decide where the time you have saved can create more value.
Each loop strengthens the others. Better instructions support better results. Reliable results create a stronger foundation for automation. Useful automation frees capacity for the next improvement.
The distinction matters: each execution needs a stopping point; the opportunity to improve does not. You still define what “good” means, set limits, and decide when the work is ready.
For leaders stuck between promising pilots and everyday results, this offers a practical way forward. You do not need to automate an entire function before creating value. Start with one useful task, make it reliable, and build from there.
The human decides. AI helps make the next iteration better.
Loop One: Use AI to Improve What AI Produces
A single prompt can produce a useful answer. But when a task involves analysis, judgment, and several deliverables, asking AI to do everything at once makes the result harder to control.
The first loop starts by breaking that task into a chain of prompts, with a clear purpose for each step.
Consider a monthly management report. Instead of asking AI to “analyze the data and write the report,” you guide it through a sequence:
- Analyze the inputs: Identify trends, changes, and gaps in the available data.
- Identify the issues: Separate meaningful developments from routine fluctuations.
- Develop recommendations: Connect proposed actions to the evidence.
- Draft the report: Present the findings in a format your leadership team can use.
- Evaluate quality: Check the report against defined criteria.
You are still working interactively with AI. Between steps, you can challenge an interpretation, add context, or reject a recommendation. The chain makes those decisions visible instead of burying them inside one long answer.
The Quality Gate Creates the Loop
The final step is not simply asking AI, “Is this report good?”
That question leaves too much undefined. A useful quality gate specifies what good means:
- Are factual claims supported by the source data?
- Are material issues covered?
- Does each recommendation include evidence, an owner, and a proposed next action?
- Are uncertainties and missing information clearly identified?
Use AI to evaluate the draft against those criteria. Then use the findings to return to the step that needs work.
If a recommendation is vague, revisit recommendation development. If a conclusion lacks evidence, return to the analysis. If information is missing, obtain it or flag the limitation—do not ask AI to fill the gap with a more confident sentence.
The loop becomes: generate → evaluate → revise → human approval.
This is more useful than repeatedly asking, “Make it better.” You are diagnosing a specific weakness and correcting it where it originated.
AI Feedback Is Not Proof
AI can help spot inconsistencies, omissions, and weak reasoning in its own output. But it can also overlook, or repeat, its earlier mistakes.
Its evaluation is feedback, not independent verification. Critical facts still need checking against trusted sources. You define the quality criteria, resolve ambiguous findings, and decide whether the result is ready.
Set a stopping condition, too: an agreed quality threshold, a limit on revision cycles, or escalation when the process cannot resolve an issue. The aim is a usable result, not perpetual polishing.
The first loop improves the work in front of you. The next loop improves the instructions that produced it.
Loop Two: Use AI to Improve the Instructions
When an AI output falls short, our first instinct is usually to fix the answer.
But if the same weakness keeps appearing, the answer may not be the real problem. The instructions may be.
The second loop moves one level upstream: use AI to improve the prompts, the prompt chain, and the quality gate behind the result.
You do not have to become an expert prompt writer before doing this. Start with your existing instructions, an example of the output, and a clear explanation of what failed. Ask AI to help diagnose the gap.
For example:
You are a prompt design and optimization expert. Review this prompt chain and the report it produced. The recommendations are too generic for our operations team. Identify which instructions contributed to that problem, what context is missing, and what changes we should test. Output the results in a table with existing content, target content, issue, change suggested in the prompt.
This turns an unsatisfactory result into evidence for improving the process.
Better Prompts Need Better Context, not Just More Words
A longer prompt is not automatically a better prompt. The goal is to make the task clearer, not bury it under instructions.
AI can help you identify what each step needs:
- Context: Who will use the output, and what decision will it support?
- Evidence: Which sources should AI use, and what should happen when information is missing?
- Constraints: What operational, commercial, or regulatory boundaries apply?
- Output requirements: What must the result contain to be useful?
- Quality criteria: How will you decide whether the work is acceptable?
Return to the monthly management report. If its recommendations are consistently vague, “be more specific” is a weak correction. A stronger instruction might require each recommendation to name the affected property or team, cite supporting evidence, propose an action, and identify an owner, or flag that ownership needs a human decision.
AI can help draft those instructions. You decide whether they reflect how your business actually works.
Improve the Chain and the Gate Together
Sometimes the problem is not an individual prompt. It is the sequence.
Perhaps the report is drafted before the key issues have been validated. Perhaps recommendations are developed without enough operational context. Ask AI to review the chain for missing inputs, unnecessary steps, and decisions that need human involvement.
Then review the quality gate. Does it test what matters, or merely reward a polished document?
A report can be clear, concise, and completely unhelpful. If actionable recommendations matter, the evaluation must check for them explicitly.
The second loop therefore becomes:
Run the chain → diagnose weaknesses → improve the instructions → test again.
Test proposed changes on representative examples, including difficult cases—not just the report that exposed the problem. Compare the results against the same quality criteria. Keep changes that improve performance, and reject those that merely make the prompt more elaborate.
This is where improvement starts to compound. Instead of correcting the same flaw every month, you strengthen the process that produces every future report.
Loop one improves this result. Loop two makes better results more repeatable.
Loop Three: Use AI to Build—and Improve—the Agent
Once your prompt chain produces reliable results, the next question becomes practical: which parts still need your involvement, and which can run without it?
That is the starting point for the third loop. Use AI to help turn a proven interactive process into a workflow or agent, then use AI to improve that automation.
The order matters. Automating an unreliable chain does not make it reliable. It makes its weaknesses repeat faster.
Turn the Chain into an Executable Workflow
An interactive process can rely on you to fill gaps. You supply a missing document, explain an ambiguous instruction, or decide what happens next.
An automated workflow needs those dependencies made explicit.
Use AI to help translate your prompt chain into a workflow specification, reusable skills, or agent code. Define:
- Inputs and sources of truth: Where does the agent obtain information, and which sources take precedence?
- Steps and tools: What must it do, in what order, and with which permissions?
- Quality gates: What checks must the output pass?
- Human decisions: What requires review, approval, or additional context?
- Stopping conditions: When should it finish, retry, or escalate?
For the monthly management report, the agent might retrieve approved data, identify significant changes, draft recommendations, and evaluate the report. Missing data or unsupported conclusions should trigger an exception—not an invented explanation.
You are not simply removing the human from the chain. You are designing where human judgment belongs.
Change How the Work Gets Done
Building an agent is also an opportunity to reorganize the process, rather than copy every manual step.
For some tasks, that means reversing the usual approach. Instead of producing one recommendation and repeatedly polishing it, the agent can generate several viable options, compare them against defined criteria, and develop the strongest candidate.
For example, it could compare responses to rising overtime costs by likely impact, implementation effort, and operational risk before drafting its recommendation.
The aim is not to explore every possible option. It is to consider a useful, bounded set—and evaluate before committing.
Use Failures to Improve the Automation
Even a well-designed agent will encounter cases you did not anticipate.
When it underperforms, collect the evidence: its instructions or code, execution logs, relevant inputs, expected behavior, and actual output. Use AI to help locate the failure and propose a correction.
Did the agent select the wrong source? Skip a check? Misinterpret a tool response? Apply an unsuitable evaluation criterion?
That diagnosis is more valuable than asking, “Can you make this agent better?”
The loop becomes: build → run → evaluate → improve → retest.
Review proposed changes and test them before deployment, including checks that previously successful cases still work. Use an approved environment when sharing code, logs, or business data for analysis.
This is not an agent endlessly rewriting itself in production. It is a controlled improvement cycle, with permissions, retry limits, and human oversight.
Loop one improves the output. Loop two improves the instructions. Loop three improves the system that carries out the work.
Loop Four: Reinvest Saved Time in the Next Opportunity
When an agent starts delivering reliable results, it creates something valuable beyond its output: capacity.
The fourth loop begins with a business question: what should we do with the time we have recovered?
Some of it should go back into the work that needs human attention: supporting clients, coaching colleagues, or making difficult decisions. But reinvest a portion in designing the next useful automation, and the improvement cycle can accelerate.
One agent creates room to build the next. That agent creates further capacity. Each cycle expands what a person or function can accomplish.
This does not happen automatically. Saved time can easily disappear into more meetings, more admin, or the next urgent request. Reinvestment needs to be deliberate.
Use AI to Help Choose What Comes Next
Most business users do not lack ideas. They lack a clear way to choose between them.
You might have ten candidates: recurring tasks to accelerate, frustrating processes to simplify, or new capabilities your team has never had time to develop.
Use AI to help compare those opportunities against practical criteria:
- Business value: What outcome would improve, and for whom?
- Frequency and effort: How often does the work happen, and how much time does it consume?
- Feasibility: Are the inputs, tools, and sources of truth available?
- Risk and oversight: What could go wrong, and where must a human decide?
Ask AI to expose assumptions and missing information before it ranks the options. A confident score based on guessed inputs is not a sound investment decision.
AI helps structure the choice. The business user owns it.
Build Beyond the Existing Task List
Return to the monthly management report. Once that workflow saves measurable time, the next opportunity might be another reporting task.
But it could also be something new: monitoring operational exceptions between reports, preparing targeted questions for property managers, or identifying issues early enough to act before month-end.
That is an important shift. AI is not only helping you complete yesterday’s workload faster. It can help you develop capabilities that previously cost too much time to sustain.
Choose one manageable opportunity, define its success criteria, and work through the earlier loops again: build the chain, improve the instructions, and automate the parts that are ready.
The fourth loop becomes: save time → identify opportunities → prioritize → build → measure → reinvest.
Measure the net benefit, including review and maintenance effort. The cycle only compounds if the capacity gained is real.
There is no fixed endpoint to finding better ways to work. But each new automation still needs a clear purpose and a justified place in the business.
The goal is not an ever-growing collection of agents. It is an expanding ability to deliver useful work, with people deciding what matters next.
Loop one improves the output. Loop two improves the instructions. Loop three improves the automation. Loop four turns the time saved into the next opportunity.
The Improvement Is Infinite. Each Execution Is Bounded.
These four loops are not separate AI projects. They are layers of the same approach:
Better outputs → Better instructions → Better agents → Better choices about what comes next.
Each layer strengthens the others. Evaluating an output reveals weaknesses in your prompts. Improving those prompts makes automation more reliable. Reliable automation creates capacity to pursue the next valuable opportunity.
That is what makes the loops powerful—not endless execution, but continuous learning carried forward.
Each task still needs a finish line. Each agent needs clear permissions, stopping conditions, and escalation rules. Each new automation needs a business reason to exist.
The opportunity to improve remains open. The authority to act remains bounded.
For leaders facing AI paralysis, this offers a practical alternative to another ambitious roadmap with no operational results. Start with one recurring task. Define what good looks like. Build a prompt chain, test its quality gate, and improve it through real use. Automate only when the process is ready.
Then measure the value—and decide where to go next.
You do not need a perfect system to begin. You need a useful first loop and the discipline to learn from it.
The human decides. AI helps improve the result, the process, and the next move. Build momentum first—transformation will follow.
Executive Frequently Ask Questions
Q1: What are “infinite loops” in an AI strategy?
A: System in Motion uses “infinite loops” to describe four nested cycles of AI improvement: improving outputs, improving prompts, improving automation, and choosing the next opportunity. The concept is continuous improvement—not an AI agent running indefinitely. Each execution remains bounded, while learning informs the next cycle.
Q2: How can executives move from AI pilots to operational value?
A: Start with one recurring business task, define measurable success criteria, and build a prompt chain with a quality gate. Improve it through real use before automating it. Once the automation delivers a verified benefit, reinvest some of the recovered capacity in the next opportunity. This creates a practical path from experimentation to daily value.
Q3: Why use a prompt chain instead of a single prompt?
A: A prompt chain separates a complex task into explicit steps, such as analysis, recommendation development, drafting, and evaluation. This makes intermediate decisions easier to inspect and weaknesses easier to correct. Prompt chains can improve control and reliability for complex work, although simple tasks may only need one prompt.
Q4: What is an AI quality gate?
A: An AI quality gate is a checkpoint that evaluates an output against defined acceptance criteria. These might include factual accuracy, completeness, evidence, and actionable recommendations. The gate determines whether the work can proceed, needs revision, or requires human review. It makes quality an explicit requirement rather than a subjective impression.
Q5: Can AI reliably evaluate its own output?
A: AI can help identify omissions, inconsistencies, and weak reasoning, but its review is not independent proof of correctness. It may repeat or overlook its original mistakes. Critical claims need verification against trusted sources, and consequential decisions require appropriate human review. AI evaluation supports quality control; it does not replace accountability.
Q6: How can AI help employees write better prompts?
A: Employees can give AI their existing prompts, representative outputs, and an explanation of what failed. AI can then suggest clearer instructions, missing context, better output requirements, and stronger evaluation criteria. Employees should test those changes against representative cases. Better prompts are more precise and useful—not necessarily longer.
Q7: When should a company turn a prompt chain into an AI agent?
A: A company should consider automation when the prompt chain performs reliably on representative cases and its inputs, tools, quality criteria, and exception paths are understood. Automate the steps that can operate within clear boundaries. Keep ambiguous or consequential decisions under human control. Automation readiness depends on demonstrated performance, not enthusiasm for the technology.
Q8: What should executives require before deploying an AI agent?
A: Require a defined business purpose, approved data sources, appropriate access permissions, tested quality gates, and clear human approval boundaries. The agent also needs stopping conditions, retry limits, escalation rules, and monitoring. An accountable owner should oversee performance and changes. These controls help turn a promising demonstration into a manageable operational capability.
Q9: How can AI help improve an existing workflow or agent?
A: AI can analyze an agent’s instructions or code alongside execution logs, inputs, expected behavior, and actual results. It can help diagnose failures and propose targeted changes. Those changes should be reviewed and tested before deployment, including checks that previously successful cases still work. Use approved environments when sharing business data, code, or logs.
Q10: Does continuous AI improvement require agents to modify themselves autonomously?
A: No. The infinite-loops approach works through controlled improvement cycles. AI can recommend changes, while people review, test, and authorize them. Continuous improvement does not require unrestricted self-modification or endless execution. The objective is better performance with clear accountability, not maximum autonomy.
Q11: How should executives prioritize AI automation opportunities?
A: Compare opportunities by business value, frequency, current effort, feasibility, data readiness, risk, and oversight requirements. AI can help structure the comparison and identify missing information, but rankings should use validated inputs rather than invented assumptions. Prioritize a manageable opportunity with measurable value and a responsible business owner.
Q12: How should a company measure the value of an AI agent?
A: Compare performance against a baseline established before deployment. Measure relevant outcomes such as cycle time, output quality, rework, cost, or service responsiveness. Include human review, maintenance, and exception-handling effort when calculating benefits. Time saved is recovered capacity; it becomes financial value when the business reduces costs or uses that capacity productively.
Q13: How can AI automation create compounding business value?
A: Compounding value can emerge when a successful automation frees capacity that is deliberately reinvested in the next useful workflow. Each cycle also builds reusable knowledge about prompts, quality gates, and agent design. The effect is not automatic: benefits must be measured, maintenance accounted for, and reinvestment protected from competing demands.
Q14: How do AI strategy and governance work together in this approach?
A: Strategy defines which outcomes matter and where AI should create value. Governance defines the data access, quality standards, approval boundaries, and accountability needed to pursue those outcomes responsibly. In System in Motion’s terms, “Governance without strategy is a cage. Strategy without governance is a gamble.” The four loops connect practical execution with both.
Q15: What is the first step for an executive adopting the infinite-loops approach?
A: Select one recurring task with a clear business owner, accessible inputs, and a measurable outcome. Define acceptable quality, establish a baseline, and test a prompt chain with human review. Improve the process before automating it. The aim is a reliable first result that creates momentum—not a perfect organization-wide system before any value is delivered.
We are Here to Empower
At System in Motion, we are on a mission to empower as many knowledge workers as possible. To start or continue your GenAI journey.
You should also read
Where Should Your Company Run AI? Public API, Private Cloud or On-Premises
Article 25 minutes readLet's start and accelerate your digitalization
One step at a time, we can start your AI journey today, by building the foundation of your future performance.
Book a Training